Last winter a friend messaged me at 2am saying his blog had been down for six hours before he noticed. He sounded aggrieved about it: the server had monitoring installed. He opened the dashboard and everything looked fine. CPU flat, memory comfortable, disk half empty.
I asked him to send the screenshot. Nothing wrong with it. The machine really was alive and well. The problem was that his Nginx container had exited around 2am, nothing on the host was watching for that, and every remaining resource metric looked perfectly calm. The server was very healthily doing nothing at all.
He is not the only person who has fallen into this. When people pick a self-hosted monitoring tool, they compare which one is lighter, which UI looks nicer, which repo has more stars. Very few start with the question that actually decides the answer: what am I trying to find out?
Beszel, Netdata and Uptime Kuma show up together in almost every self-hosting recommendation thread, which makes them look like direct competitors. Install all three and you discover they answer three different questions.
Beszel answers “are my machines OK right now?”
Netdata answers “what exactly happened on this box during that one second?”
Uptime Kuma answers “can a user open my website?”
My friend had installed resource monitoring to solve an availability problem. Nothing wrong with the tool. Wrong pairing.
Resource monitoring and uptime probing are not the same job
Get this layer straight and the rest of the choice stops being murky.
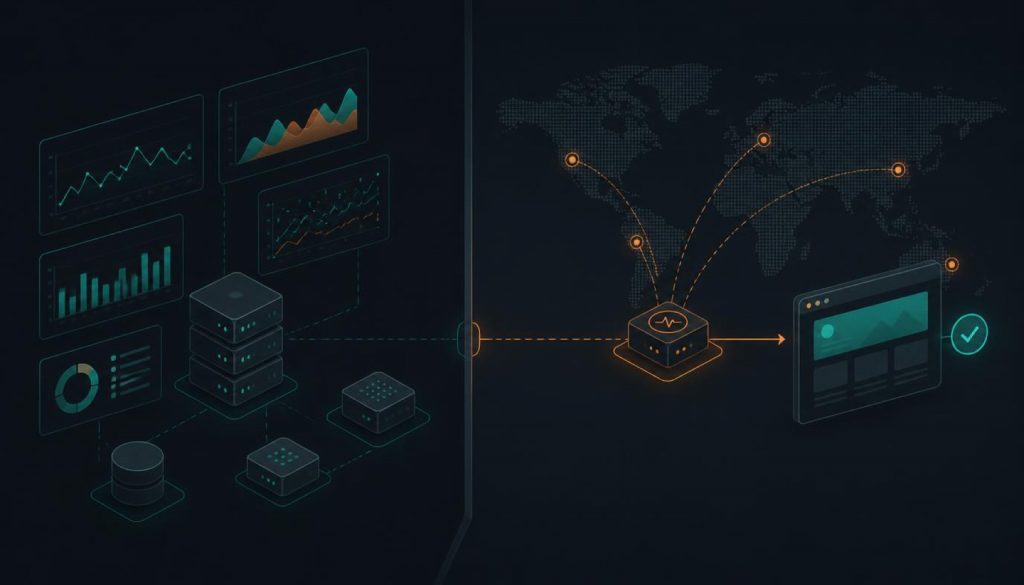
Resource monitoring stands inside the machine looking outward. It runs a collector process on every host you care about, reads /proc, reads hwmon sensors, reads the Docker socket, and reports CPU, memory, disk I/O, network throughput, temperature. Its view is the host’s vital signs.
Uptime probing stands outside looking in. It does not care what happens inside your box. It just keeps knocking on the door: did the HTTP request return 200? Did the TCP port accept a connection? Does it answer ping? How many days until the certificate expires? Its view is whether a user can actually use the thing.
These two views overlap somewhat, and neither substitutes for the other. Healthy resources plus a dead service is the single most common blind spot. A crashed process, a port swallowed by a firewall rule, an expired certificate, DNS drifting, an upstream CDN having a bad day: on a resource graph every one of those looks like “all normal.”
The reverse holds too. A probe tells you the site is returning 502. It does not tell you why. Whether the OOM killer took your process, whether the disk filled up, whether something went into a CPU spin, that needs the historical curves from the resource side.
Once that distinction is clear, each tool lands in an obvious place.
Beszel: the answer for “I have a handful of machines”
Beszel is the youngest of the three. The repo was created in July 2024 and now sits above 25,000 stars, written in Go, MIT licensed. Author henrygd describes it plainly: lightweight server monitoring with historical data, Docker stats and alerts.
It ships as a hub plus agents. The hub is a web app built on PocketBase that holds the dashboard and the system list. An agent runs on each monitored machine and pushes metrics to the hub. Data lands in the hub’s SQLite, so there is no separate time-series database to babysit.
That design carries a practical benefit: agents never need public internet exposure. Hub and agent authenticate with a key pair, and the connection can even run over a Unix socket. You do not open a dashboard port on every box just to see graphs.
What does setup feel like? The official guide hands you a docker-compose file that starts the hub and a local agent together. Change APP_URL, run docker compose up -d, open port 8090, create the admin account. Adding a second machine means copying the key and token the hub generates into that machine’s agent environment variables. No config file syntax to learn, no scrape targets to reason about.
It collects more than the word “lightweight” suggests: host and per-container CPU, memory and network; disk usage and I/O across multiple partitions and devices; load average; temperature sensors; fan speed; Nvidia, AMD and Intel GPU utilisation and power draw; battery charge; plus S.M.A.R.T. drive health and ZFS pool status. Alerts can be configured on CPU, memory, disk, bandwidth, temperature, fan speed, load average and online status. Multi-user access and OAuth / OIDC login are both there, and backups can go to disk or S3-compatible storage. The features page lays all of it out.
What it does not do is equally clear. No sub-second sampling, no service discovery, no digging into your MySQL or Redis internals, no external probing. It is a dashboard, not a microscope.
My read is that Beszel fits the case where you have somewhere between a few and a couple dozen machines, all your own VPS boxes or a homelab. What you want is one page showing every machine’s health and a notification when a disk is about to fill up, rather than a platform for root cause analysis.
Netdata: when you need the scene of the crime, second by second
Netdata plays in a different weight class. Over 80,000 stars, around since 2013, GPL-3.0, with Go at its core now. Its repo description no longer even says “monitoring” and instead reaches for full stack observability.
Its defining difference is not feature count. It is time resolution. Netdata samples per second by default, and stores that history per second too. In a debugging session that difference decides outcomes.
Picture this: your API goes noticeably slow for a few seconds every ten to fifteen minutes. Users complain occasionally, and you can never reproduce it yourself. Viewed through minute-granularity monitoring, those few seconds get averaged into the whole minute and the graph shows a flat, unremarkable line. Only per-second sampling surfaces the spike, and then you notice it lines up with a cron job’s I/O peak. Case closed.
The other Netdata trait is zero-configuration auto-discovery. After installation it scans what is running on the box. Nginx present, it collects Nginx metrics. PostgreSQL present, it collects PostgreSQL. Containers present, it collects each one. No hand-written exporter configs. Open http://host-ip:19999 and several hundred charts are already moving.
There is a price at both ends.
One end is resource usage. Per-second sampling across thousands of metrics on a single machine means the process itself uses noticeably more memory and CPU than a minute-interval agent like Beszel. Netdata upstream keeps optimising, and there are knobs to reduce collection frequency and trim collector modules, but the default configuration aims for maximum data coverage rather than minimum footprint. On a 1GB VPS you will feel it there.
The other end is multi-machine management. Netdata agents work independently, one dashboard and one alert configuration per machine. Three machines, you keep three tabs open. Thirty is unworkable. The official answer is Netdata Cloud, where data stays on your servers and Cloud handles real-time querying plus a unified pane, free up to 5 nodes. Beyond that the Business tier bills per node, and the pricing page lists $4.50 per node per month billed annually, adding RBAC, SSO, centralised configuration management and enterprise notification integrations. Fully on-premise Enterprise starts at 200 node licences and requires talking to sales.
The model is interesting in its own right: the agent is fully open source and free at any node count, but consolidating many machines into one pane is the commercial hook. You can also build parent-child aggregation yourself using the agent’s streaming feature, documented upstream, if you would rather configure it by hand.
So I would frame Netdata as your debugging instrument, not necessarily your daily dashboard. Install it on the machines that matter and go dig through those few seconds when something breaks. That usage has the best return on the overhead.
Uptime Kuma: the only one standing outside knocking
Back to my friend’s 502. What he actually needed was Uptime Kuma.
It has the most stars of the three at over 91,000, MIT licensed, written in Node.js by louislam. Its job is narrow: repeatedly check from outside whether something is reachable, and notify you when it is not.
The check types cover more ground than you might expect. The README lists HTTP(s), TCP port, HTTP keyword matching, HTTP JSON query, WebSocket, ping, DNS record, push (reverse heartbeat), Steam game server and Docker container. Minimum check interval is 20 seconds.
Keyword matching deserves its own mention. Status codes alone are not enough. A WordPress site that cannot reach its database will often still return 200 with “Error establishing a database connection” rendered on the page. Configuring a keyword monitor that looks for a string only present when things work is what turns the check into a real answer about whether the page is useful.
Notification coverage is the other strong suit. Telegram, Discord, Gotify, Slack, Pushover, SMTP email, with more than 90 notification service integrations maintained in the repo. Your obscure push tool of choice is probably in there.
It also ships status pages, multiple ones, mappable to different domains. If you owe customers or a community a public “is the service up” page, that comes out of the box with nothing extra to deploy. Certificate expiry days, ping charts, proxy support and 2FA are all included.
Installation is a single docker run or a compose file, with data on a local volume by default. The official docs and the repo compose config can be copied almost verbatim. One caveat the project states explicitly: network file systems like NFS are not supported for the data directory, so map a local directory or volume.
What it does not do: collect any host internals. No CPU chart, no memory curve, no idea how much disk you have left. It is a tireless door-knocker and nothing more.
One deployment detail gets overlooked and it matters on principle: Uptime Kuma should not run on the machine it monitors. Same box means that when the machine goes down the prober dies with it and no notification leaves the building. You get the worst possible outcome, total silence, no alert at all. Put it on a different VPS, or on a small always-on box at home, and it starts earning its keep.
Side by side
A table makes the differences easier to hold in one glance. Worth flagging that the resource footprint row can only give you an order of magnitude. Real numbers correlate strongly with how many containers you run, how many metrics you collect and how much history you retain, so any specific figure divorced from configuration is meaningless.
| Dimension | Beszel | Netdata | Uptime Kuma |
|---|---|---|---|
| Positioning | Multi-host resource dashboard | Single-host deep observability | External availability probing |
| Vantage point | Inside the machine | Inside the machine | Outside the machine |
| Sampling granularity | Minute level | Per second | 20 second minimum check interval |
| Deployment | Single binary or Docker, hub plus agent | One-line script / package manager / Docker | Docker or plain Node.js |
| Setup complexity | Low | Low for one host, medium for multi-host aggregation | Low |
| Footprint magnitude | Leanest | Highest of the three | Low, grows with monitor count |
| Multi-host management | Native hub aggregation | Netdata Cloud or self-built parent-child | One instance monitors any number of targets |
| Host metrics | CPU / memory / disk / network / temperature / fan / GPU / battery / S.M.A.R.T. / ZFS | All of the above plus auto-discovered apps and services, far larger metric count | N/A |
| Service availability checks | Online status only | Health check capability but not its main job | HTTP / TCP / keyword / JSON / DNS / ping / WebSocket / Docker / push |
| Alert conditions | CPU / memory / disk / bandwidth / temperature / fan / load / status | Large set of built-in alert templates, customisable | Target down / keyword missing / certificate expiring |
| Notification channels | Email and webhook style | Agent-local notifications, enterprise integrations via Cloud | 90+ integrations |
| Public status page | N/A | N/A | Yes, multiple pages with custom domains |
| Data storage | SQLite via PocketBase | Built-in tiered time-series database | SQLite |
| Licence | MIT | GPL-3.0 | MIT |
| Hosted offering | None official | Netdata Cloud, free to 5 nodes, Business $4.50/node/month annually | None official |
| GitHub stars | ~25k | ~80k | ~91k |
The rows that matter most are not the big numbers. They are “vantage point” and “public status page.” The first two tools sit inside the machine, the third sits outside. That is what decides whether they can replace each other, and the answer is that they cannot.
So what should you actually install
One or two personal VPS boxes running a blog or small tools. Install both Uptime Kuma and Beszel. Both are cheap. Put Uptime Kuma on a different machine or an always-on device at home, watching your domain and certificate. Put the Beszel hub wherever and spread the agents. That combination covers the two real needs, knowing immediately when a service dies and knowing in advance when resources are running out, for no more total overhead than a single Netdata install.
A small team with 5 to 20 machines. Keep Beszel as the unified dashboard and Uptime Kuma for external availability. Add Netdata separately on the one or two boxes that matter most, the database and the main application node. Do not look at it day to day, go there when something breaks and you need per-second history. Resist rolling Netdata out everywhere, because you get both the resource overhead and dashboard fragmentation at once.
You have an SLA to honour. Uptime Kuma is not optional here. Its status page and availability history are the artifact sitting between you and your customers. Accept one limitation though: a single Uptime Kuma instance is a single probe location, so what you measure is availability as seen from that one network position. If your SLA is geography-sensitive, run instances in several regions or seriously evaluate a commercial multi-location probing service. That is not a flaw in Uptime Kuma, it is the inherent boundary of self-hosted single-point probing.
You already run Prometheus and Grafana. Resource metrics are largely covered, node_exporter is already doing that work. External probing in the Prometheus ecosystem usually means blackbox_exporter, which takes considerably more configuration effort than Uptime Kuma and ships no status page. Plenty of teams with Prometheus still run a separate Uptime Kuma purely for probing and the public status page, and that is not duplicated effort. Netdata can also expose metrics in Prometheus format, so if per-second data feeding your existing stack is all you want, that path works.
Is Netdata alone enough? For one machine, yes. It has the broadest capability of the three, per-second data plus auto-discovery, and it handles both daily dashboards and debugging. What it cannot fix for itself is the missing external view, so you still do not know whether a user can open your site. With multiple machines you either pay for Cloud or spend the time building streaming aggregation yourself.
The one thing to remember
Back to that six-hour outage. Had my friend been running Uptime Kuma, a Telegram notification would have reached him within two minutes. Had he been running Netdata, he would have had ample data afterwards to work out why the container exited. The Beszel-style tool he did install was not wasted either. It at least proved this was not a resource problem.
The easiest mistake in monitoring is treating “I have monitoring installed” and “I know whether my service is working” as the same statement. Between those two sits a question of vantage point, and vantage point is the thing you should settle first during tool selection and the thing most likely to get skipped.
Related reading
- GPT-5.5 Reasoning Effort Levels: How Developers Pick the Right Setting
- Cursor vs Copilot vs Claude Code vs Windsurf: Which AI Coding Tool Is Right for You in 2026?
- Wispr Flow vs Superwhisper vs MacWhisper: Picking the Right AI Dictation Tool in 2026
Stay updated with our latest AI insights